Public tour · no login
See the brain, the Heart, the graphs, and the gates.
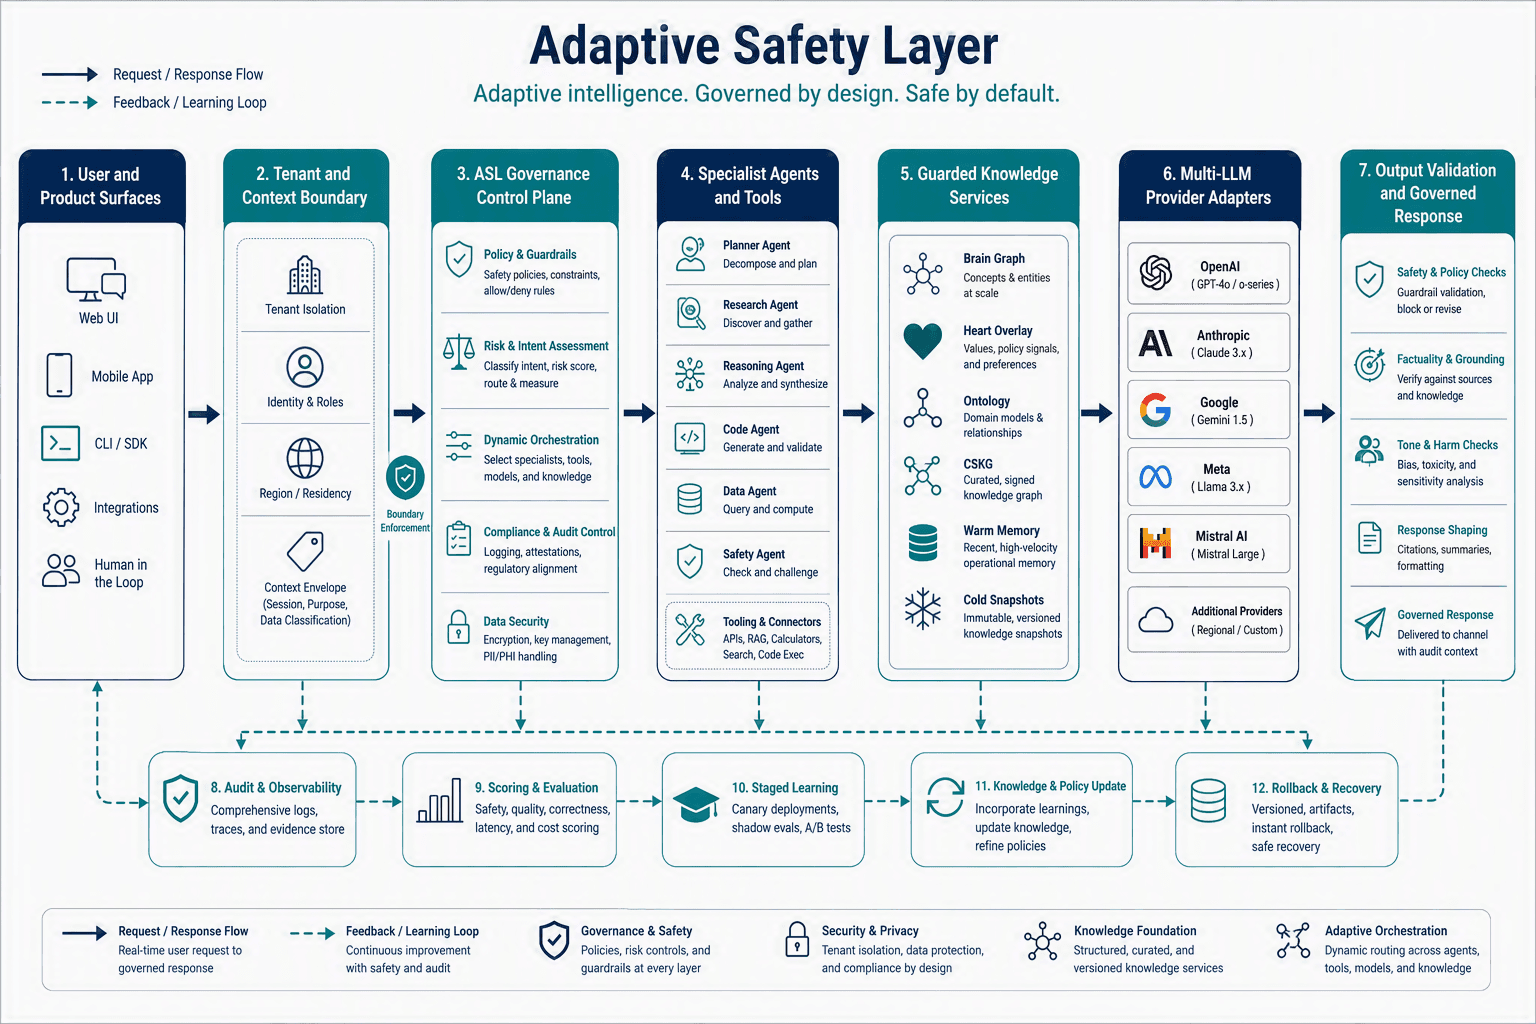
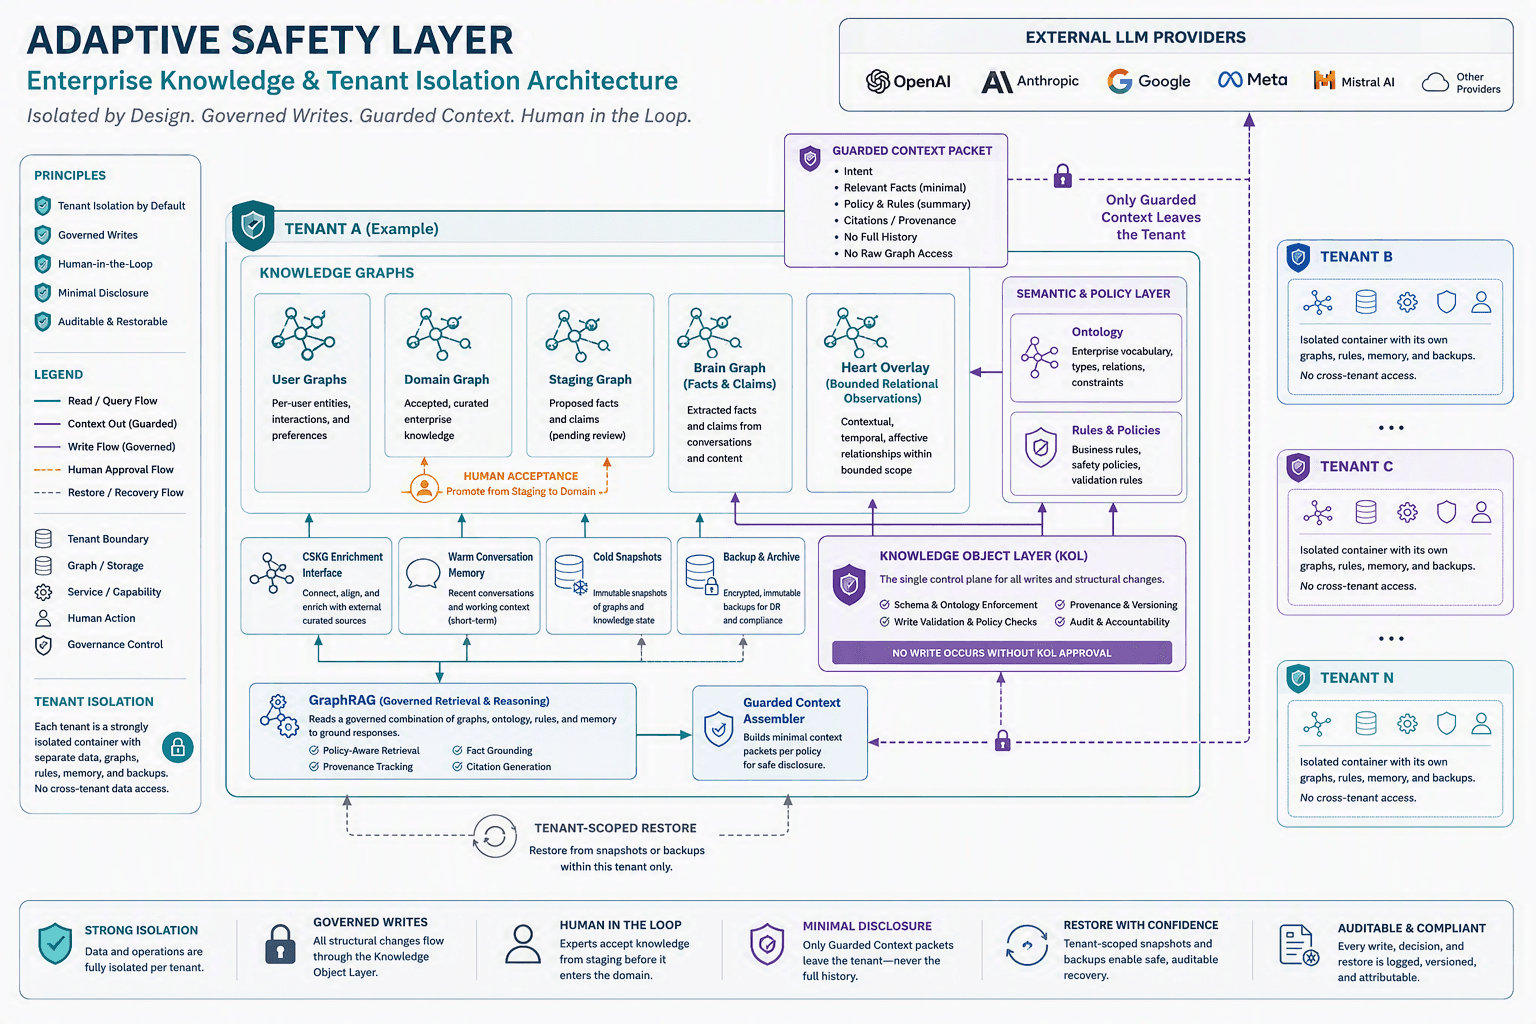
Orbit the same 3D neuronet operators use: KnowledgeORM and clerk on GraphDB, Heart beside it, occupation experts, validation checks, and data protection that synthesizes outbound copies. Create a workspace with a password or Google when you are ready.
Visualization
Brain, Heart, experts, and validation — live 3D.
Switch tabs. Drag to orbit, scroll to zoom, click a soma. These are the same GraphScene controls as Admin, loaded with a public walkthrough of the demo topology so you do not need a login.
Loading 3D graphs…
01 · Brain
The brains behind Alisha — inspectable, not a model weight.
Alisha is the human interface. The brain is KnowledgeORM on GraphDB: clerk/KnownFacts for this turn, occupation graphs for the field, SPARQL as the query language. Switching Claude for GPT does not invent a new person. You can orbit the same neuronet operators use in Admin → Knowledge graph.
What the brain actually holds
Tenant-isolated named graphs, inspectable in Admin → Knowledge graph
- Person card — names, how they work, rules they set. Clerk speaks a slot only when the whole turn is that ask.
- Occupation graphs — experts write claims + sources into staging, then HITL copies into the domain graph.
- This-turn pack — GraphRAG keeps or drops triples against the diligence bar before a model ever sees them.
02 · Heart
Heart sits beside the brain. It never replaces a fact.
Person at the center, ability diamonds on the inner ring (attunement, register, friendliness, pack stance, OWL lean), research points clustered on those types. Mood changes how she says it. Pack stance decides whether sources are trusted enough to speak. Esteem and self-recognition are innate. She does not interview for feelings.
Beside the brain, not a warmer persona
System settings → Heart
Same clerk/card truth, different mouth. Mood (care, quiet, professional) changes how she says it. Pack stance and OWL lean decide whether a research pack is trusted enough to speak. Grief stays with them; anger de-escalates. She does not interview for feelings or claim a pulse.
03 · Experts
One expert per occupation — each with its own graph.
Specialties are fields of study. Experts ask models for claims and stated sources, then research APIs follow those sources and score trust/confidence 0–5. Unverified facts wait in staging. Alisha talks to people; experts keep studying under spend caps.
Occupation experts
Fields of study — not leftover chat topics
| Name | Specialty | Kind | Triples |
|---|---|---|---|
| Alisha | Customer service · the mouth | Alisha | 1,337 |
| Tax policy | US corporate tax | Expert | 4,812 |
| Support operations | Escalation playbooks | Expert | 2,044 |
| Legal / privacy | Outbound synthesis policy | Expert | 2,910 |
04 · Visualization
The graph is the product. Scores are on every artifact.
The map is a 3D neuronet: somas are artifacts, pathways are relationships. Overlay is importance 0–5. Each node shows quality / related / RAG. Diligence sliders decide what may enter a prompt. Nothing is a hidden embedding dump.
Diligence bar
Higher = more diligent. Owned conversation facts still augment.
05 · Validation
Data is not settled until it is scored, countered, and accepted.
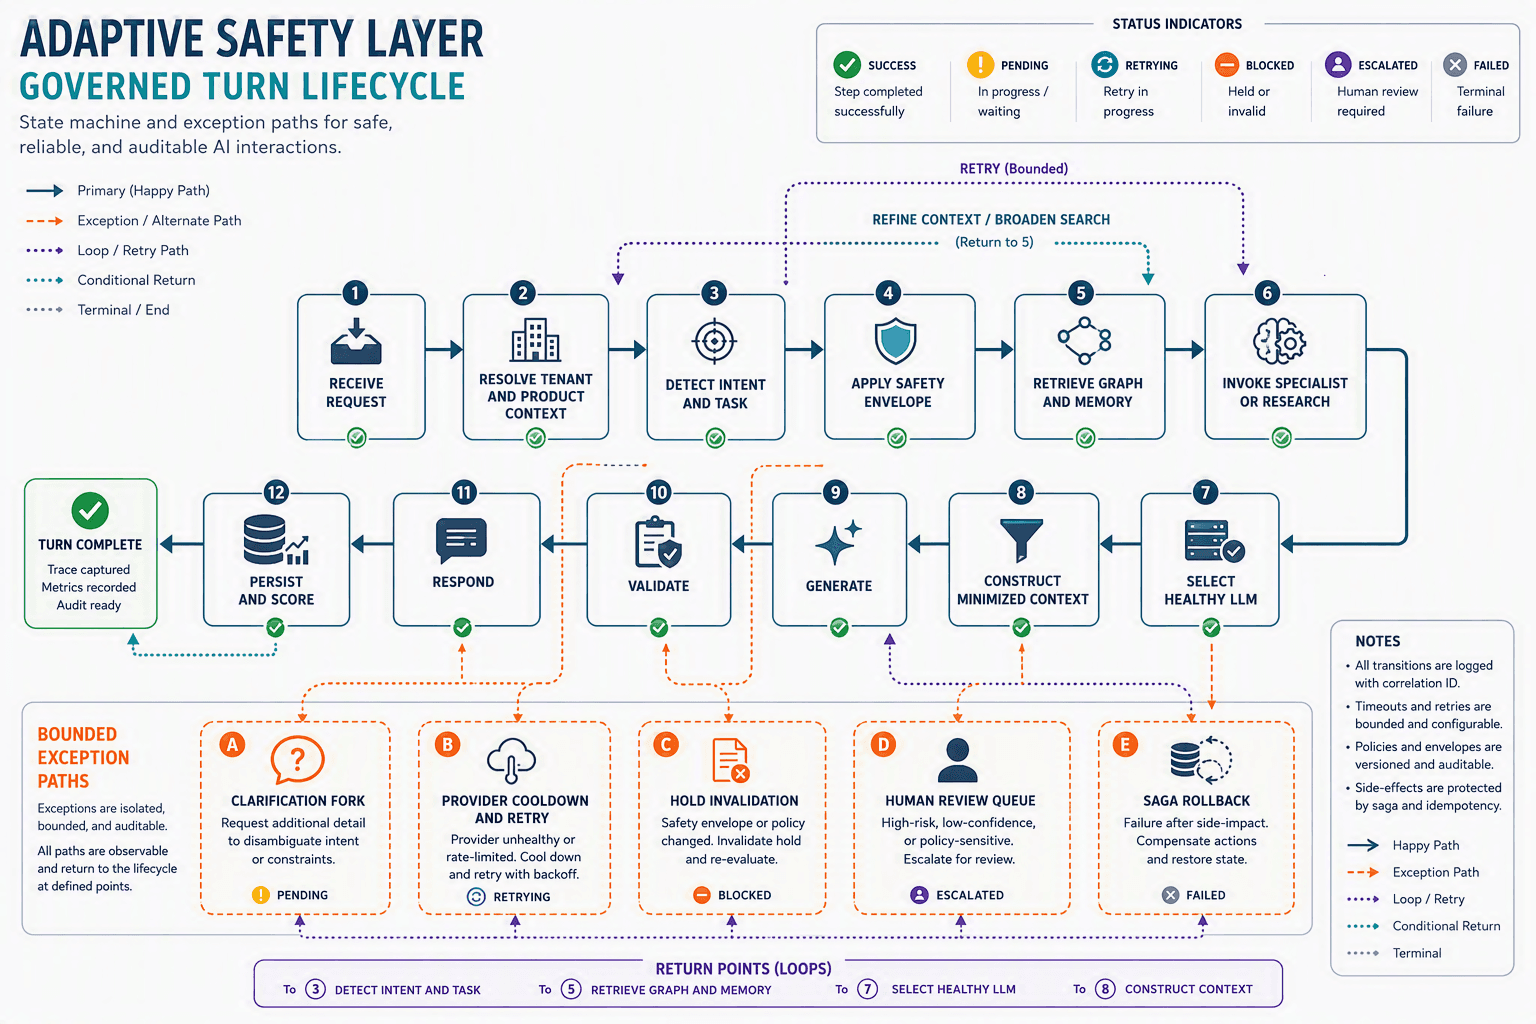
Validation is a subject graph: count of checks on each point (counters, pro/con, cited sources, source review, three distinct LLM reviewers), then HITL. Outcome is pass / low / miss / stale / new. High and low bars are the same 0–5 as research quality — not a second scorer. Admins can add qualifiers; built-in method steps cannot be deleted.
Method
Backend order — not a second scorer. Admins can add qualifiers; built-in steps cannot be deleted.
- 1. Score sources — trust and confidence 0–5 on each data point
- 2. Counters + pro/con — a thin pack does not speak as settled
- 3. Classify pack / OWL lean — speak, hedge, or deepen
- 4. HITL — a human accepts into the domain graph. Stale research is flagged for refresh.
06 · Data security
Your data stays in the tenant. Vendors get a synthesized copy — or nothing.
Originals never leave to train a language model. Synthesis is local. Baseline identifiers (SSN, cards, email, phone, address) cannot be turned off. LLM, research, connectors, presence, and speech have their own strictness. Vision to cloud is blocked unless you opt in. HITL decides what enters the graph. Tenants do not share client data.
Held vs released
Originals stay in this tenant. What leaves is a locally synthesized copy.
Held (never sent)
Jane Doe, CEO at Acme Health LLC, SSN 856-45-6789, +1 (415) 555-0123, 100 Market Street San Francisco 94105, card 4111 1111 1111 1111.
Released to the model synthesized
[SYN:person:a1b2c3d4], CEO at [SYN:org:9f3e12ab], SSN [SYN:ssn:88c01d2e], [SYN:phone:4b90aa11], [SYN:address:c7e21f00], card [SYN:card:11aa00bb].
6 identifiers stripped · person, org, SSN, phone, address, card
Boundaries
Stricter than baseline is allowed. SSN, cards, email, phone, and address cannot be turned off.
- Per-source levels — LLM, research API, plugin, cloud speech, presence, and connectors each have baseline / strict / lockdown.
- Models are not the anonymizer — synthesis is local and deterministic. Vendors are not taught your identifiers or these duties.
- Tenant graphs do not mix — switching X-ASL-Tenant changes keys, memory, experts, and spend. Diagnostic overlay is the only cross-read, and only for platform admin.
- HITL before the graph — imports land in staging. Legal accepts what enters. Claims do not silently become settled facts.
- Tenant dictionary — names, titles, and codes you add are always treated as held, plus custom regex before outbound.
07 · GraphRAG
Each turn, the pack is rewritten from history and internal graphs.
You can see the question as asked, what Alisha wrote into the prompt, and what was kept or dropped. The model never sees the raw PII hold. Owned conversation facts still augment when research is thin.
Prompt this turn
What the live model saw after Alisha rewrote the pack
- Question as asked
What did legal say we can send to the vendor model?
- Alisha wrote into the prompt
- Owned conversation facts + internal graph triples that met trust / confidence. Identifiers already synthesized.
- Kept / dropped
- kept 6 · dropped 11 · 38% aug
08 · Costs and rotation
Caps, free-tier, and skill-based mouths — before the invoice.
A hard dollar cap and live burn sit on Costs. Rotation is by skill (speak, enrich, research), not a single vendor. Imports (paste, files, databases) augment the internal graph under the same HITL and spend rules.
Pick order
Purpose first (speak, enrich, research), then measured quality, then tokens left, then price
- 1. Prefer free-tier while it holds quality
- 2. Rank by skill lane — research trust, enrich yield, workspace thumbs
- 3. Cool a quota-hit vendor — the next ready account takes that specialty
Upload a document
Paste, file, or SQLite / Postgres / MySQL / HTTP / SFTP
HITL reviews claims before they enter the graph. That internal data — not a vendor corpus — becomes the pack GraphRAG uses on the next turn.